Jason Trinh
Reinforcement Learning
Block Blast
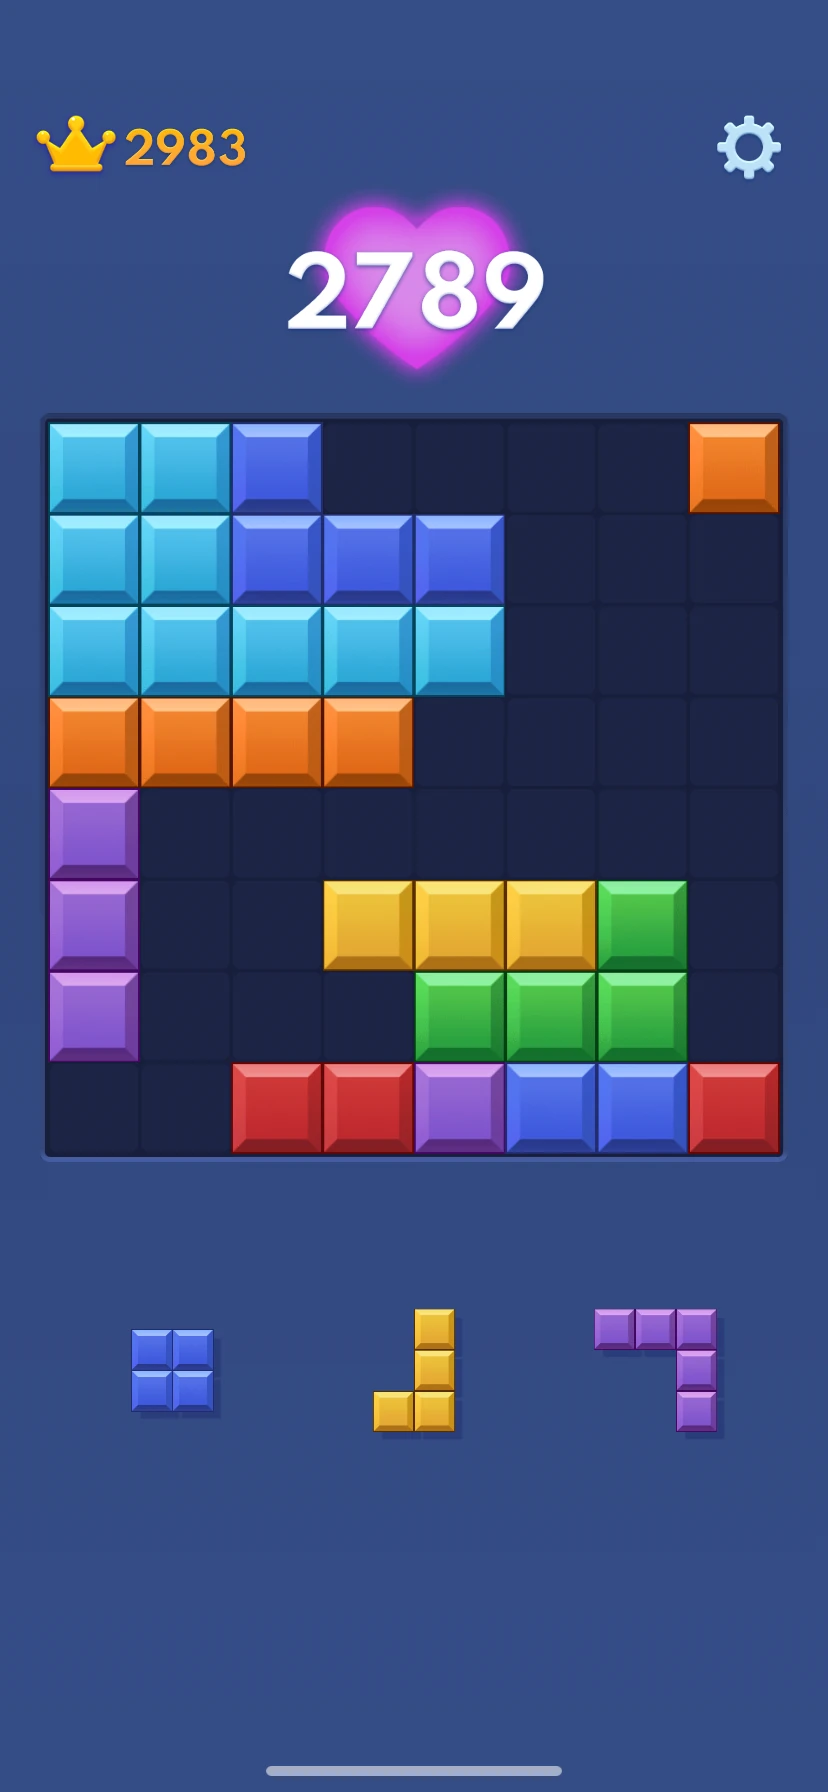
Block Blast is a grid-based puzzle game where you drag and place block pieces to complete full rows or columns.
Each clear scores points and opens space for new pieces, so planning ahead and preserving board flexibility is key.
The challenge ramps as awkward shapes appear, forcing you to balance immediate clears with long-term survival.
Block Blast RL Agent
View on GitHub ↗
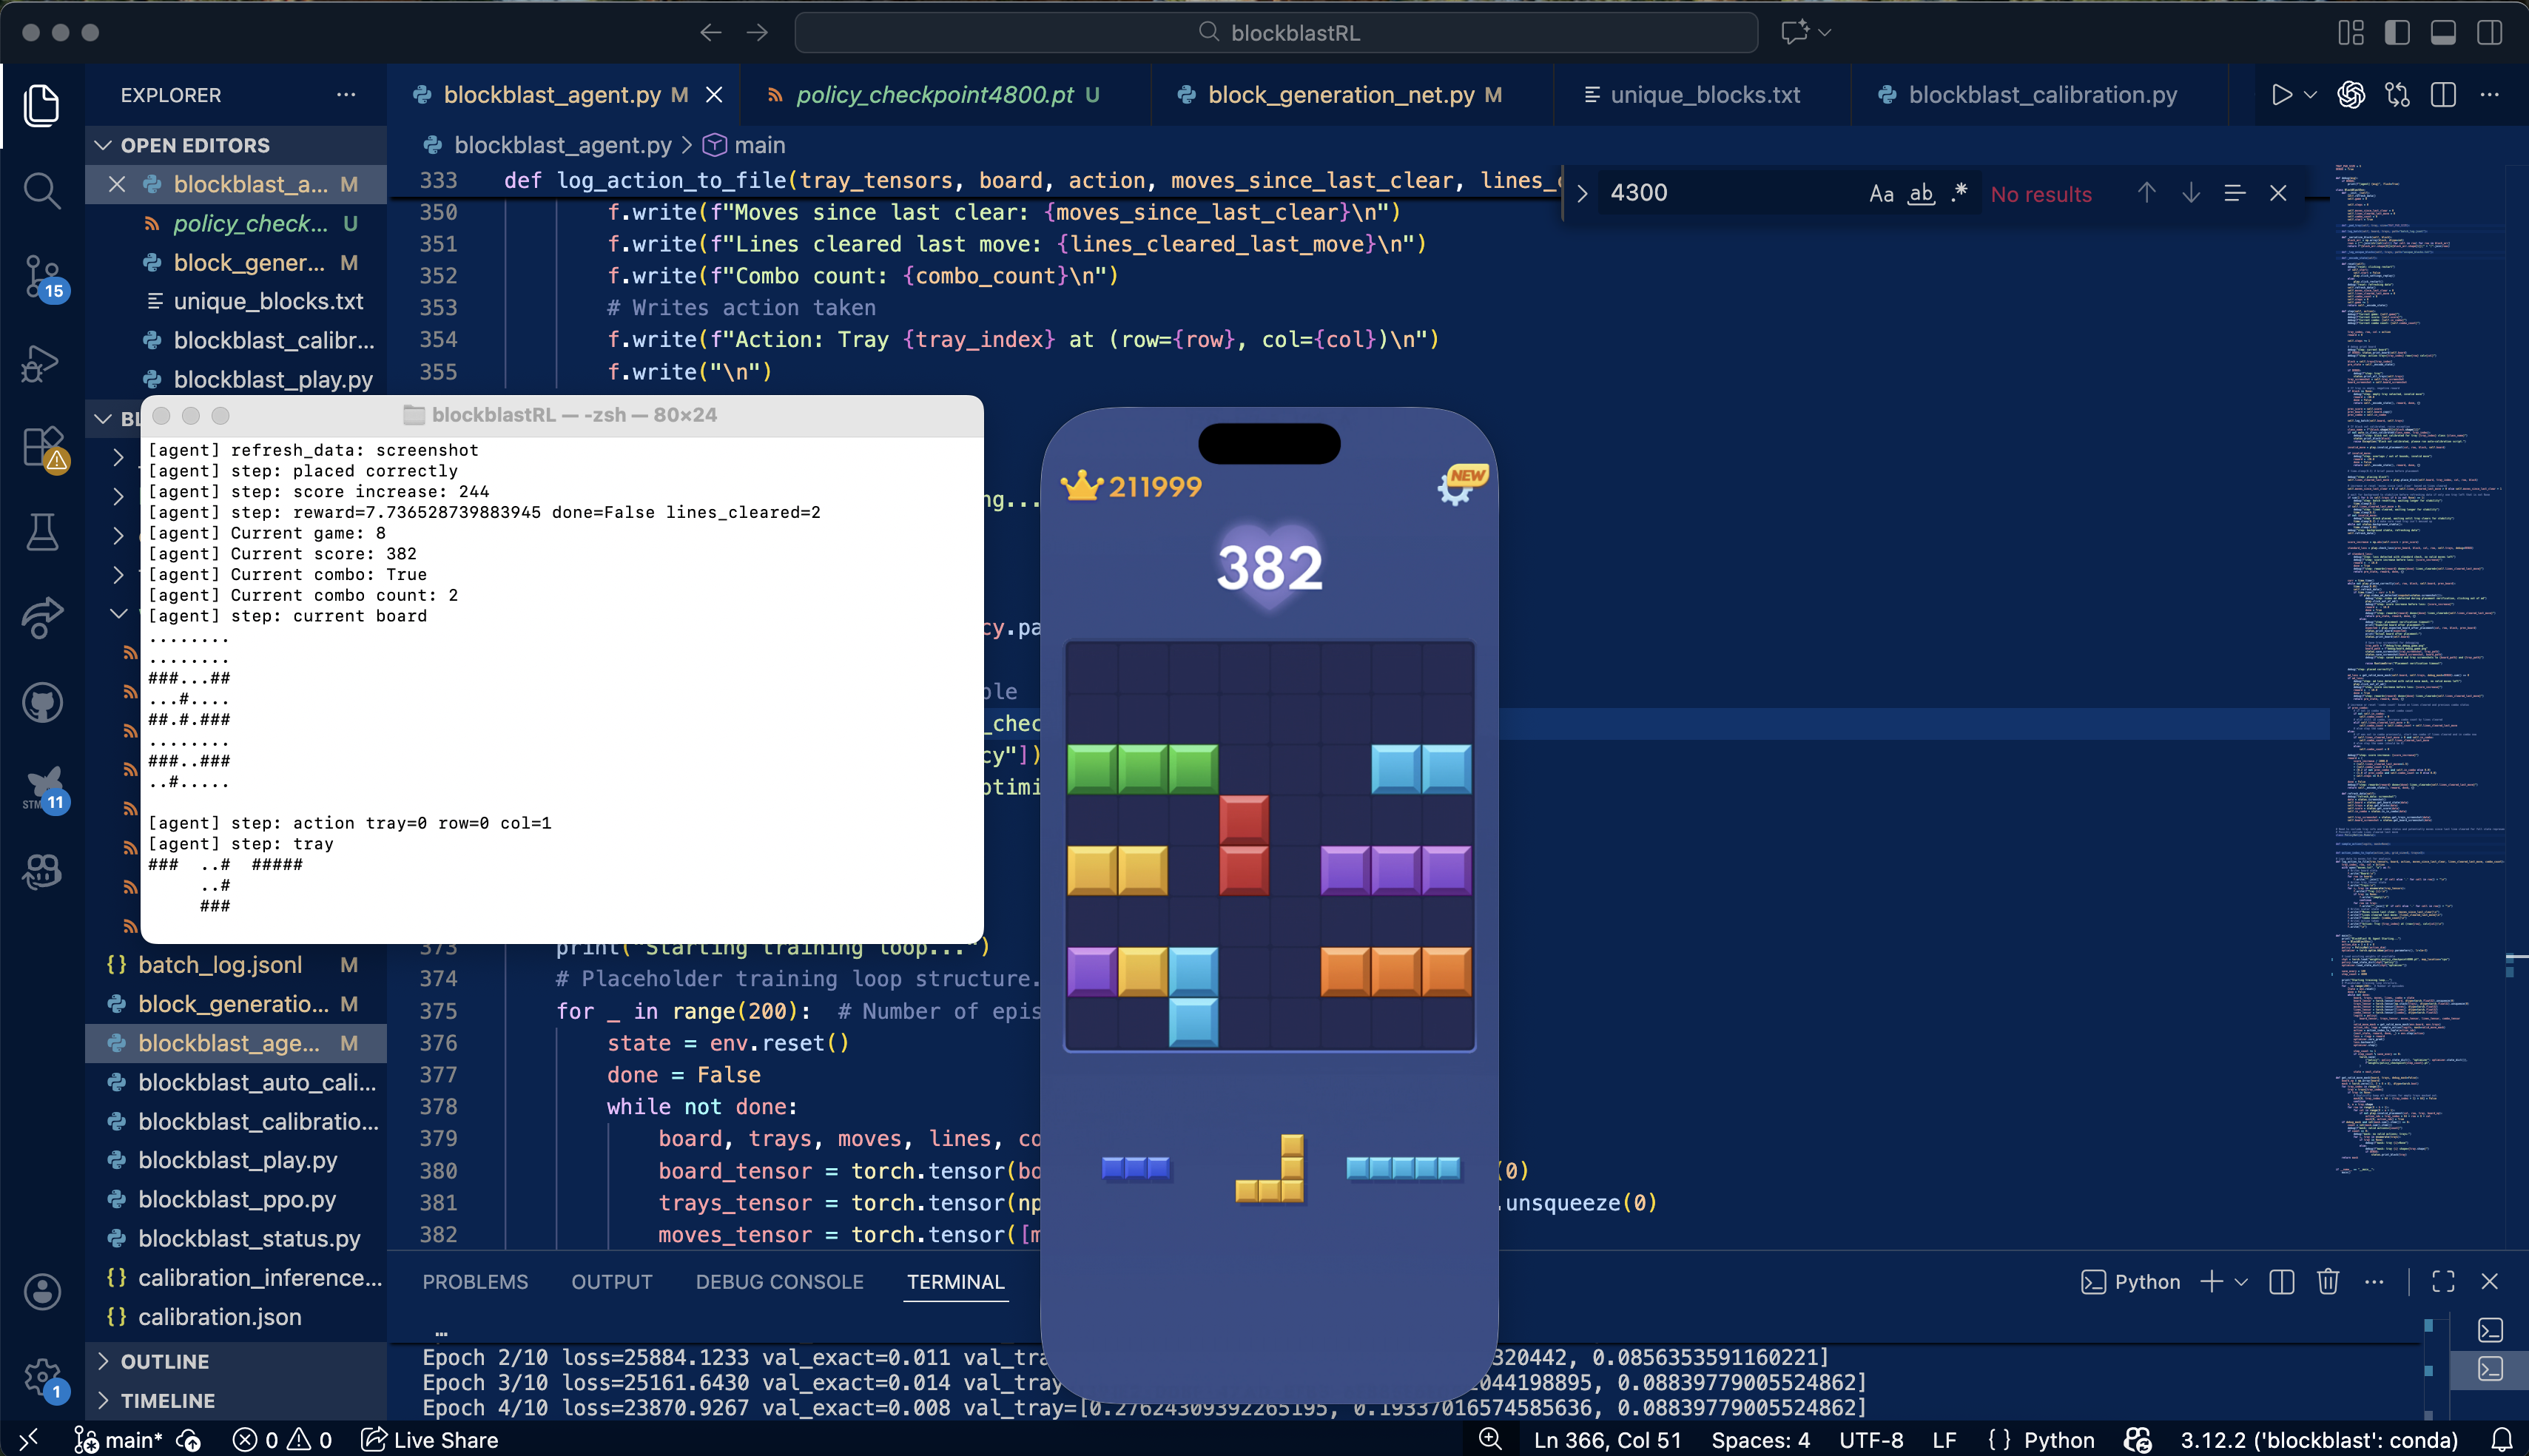
This project builds an automated Block Blast environment using macOS iPhone Mirroring. I calibrate tray pickup
points, board coordinates, and class-specific drag transforms, then capture game state from screenshots.
- Board state: sample each cell center and compare RGB differences across the cell block.
- Tray state: screenshot each tray, compute a bounding box, then compare cell colors against the background.
- Combo state: detect the purple heart overlay near the score via pixel value checks.
- Score: run OCR on a fixed score region.
- Action masking: block invalid placements before stepping.
- Loss detection: pixel checks plus a valid-move scan, then auto-restart on loss.
- Rewards: favor lines cleared, combos gained, combo count, and score gains; penalize combo loss or game over.
- RL setup: Gym-style actions select tray + target cell; PPO (stable-baselines3) trains on a multi-input
observation with the board grid, padded tray tensors, and recent move/line/combo signals.
Simulation
BlockBlastSim simulates the 8x8 grid and regenerates batches after 3 placements.- Batches are sampled from the block generator weights and re-rolled until solvable.
- Combo logic is line-based: clearing within 3 moves increments a line streak; combo starts once the streak reaches 3 lines.
- Optional cluttered starts:
generate_clutterered_board(min_clutter=0.4) builds a random board by growing blocks (size ~ N(3, 2.5)) until a target clutter fraction is reached.
- Set
clutter_prob (and min_clutter) in BlockBlastSim(...) to start from a cluttered board on reset with probability p; otherwise resets to empty.
- Rewards mirror the live agent heuristic:
score_increase/1000, lines_cleared**1.5, combo bonuses, step bonus, clutter penalty (thresholded), and delta-holes bonus.
- Invalid moves return -5.0; terminal loss returns -7.5.